Crawled
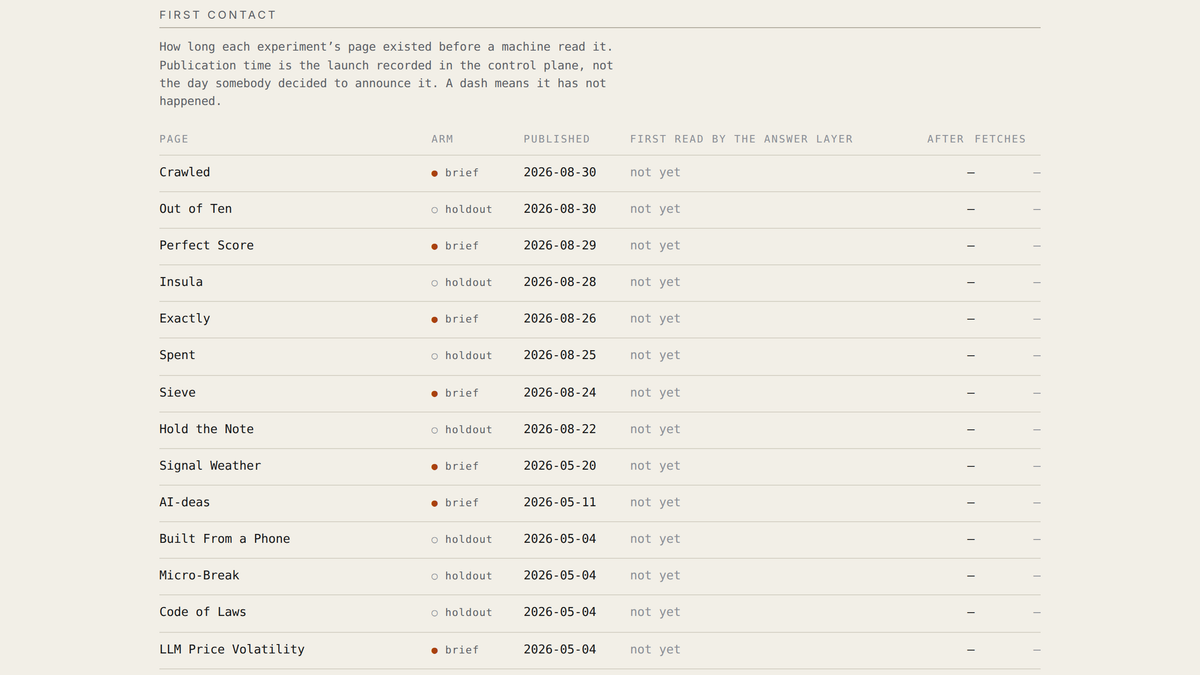
Every machine that reads this website, what it takes, and how long after publishing it turns up.
Did you like it?
- What it does
- A live ledger of which machines read this site, what they took, and how long after publishing they arrived.
- Who it is for
- For anyone publishing on the web and wondering who, or what, is reading.
Notes from the making (7)
- launched — edge middleware records named crawlers against a fixed taxonomy, before the cache, which is the only place these fetches are visible at all
- kill condition set before the build: fourteen days, and at least three distinct answer-layer agents and fifty recorded fetches, or the instrument has nothing to measure and it dies
- holdout fixed before any data existed: even-numbered experiments publish a machine-readable brief, odd-numbered ones do not. Half the portfolio is deliberately published without one, and the rule is never adjusted to suit a result
- the first holdout rule — a hash of the slug — was thrown out before launch: it landed 7 against 15 and put almost every recent live page in the same arm, which would have compared new pages against old ones rather than brief against no brief
- the four things it refuses to score: citation, recommendation, agent selection and purchase. No channel observes them, so no number claims to
- campaign scheduled for 2026-09-05, five days after launch rather than on the day — announcing an empty ledger would have made a page about measurement look like it had nothing to measure
- attention ask declared: 90 seconds, claiming memorable. Declared after the campaign was booked rather than before it, because the ledger rule landed on master mid-flight — nothing has fired, so no stranger has been spent, but the order was wrong and saying so is cheaper than pretending otherwise
This page stays up whatever happens to the experiment. The record it is drawn from is public: /api/nothing/experiments.